Uploading Data to the GPU

Until now, most of the work on STAGE VK had been focused on getting Vulkan itself running correctly.
The engine could create an instance, select a GPU, create the logical device and queues, manage a swapchain, record command buffers, synchronize frames and finally present an image to the screen. After that, I separated the rendering architecture into VulkanModule, RenderModule and EditorModule, and added the first editor tools on top of Dear ImGui.
All of that gave me a working frame.
What it did not give me was a way to actually store my own rendering data on the GPU.
That became the focus of this chapter.
Before I can start thinking seriously about meshes, vertex buffers, index buffers or imported models, the engine needs a solid way of creating Vulkan data buffers (VkBuffer), allocating memory for them and moving data from the CPU to a place where the GPU can use it efficiently. This sounded like a fairly small step when I started but it ended up teaching me a lot about Vulkan memory, synchronization and, unexpectedly, C++ resource ownership.
Note: VkBuffer
A VkBuffer is a generic linear data resource in Vulkan. What the buffer is used for depends on its usage flags. The same VkBuffer resource can be used for:
Vertex Buffer: stores vertex attributes used to build geometry (positions, normals, UVs, colors).
Index Buffer: stores indices that reference vertices when drawing indexed geometry (for example, reusing four vertices to draw two triangles).
Uniform Buffer: stores small sets of data that shaders need to read (camera matrices, light parameters, material values).
Storage Buffer: stores larger or more general-purpose data that shaders can read and, when allowed, write (particle data, object data, compute results).
Staging Buffer: temporarily holds CPU-written data before it is copied into another GPU-oriented resource (uploading mesh vertices from CPU memory to a vertex buffer).
Transfer Source: acts as the source of a copy operation (copying data from a staging buffer).
Transfer Destination: receives data from a copy operation (copying uploaded data into a final vertex or index buffer).
Note: Usage Flags
VkBuffer is a generic resource, so when creating one Vulkan needs to know what operations the buffer is expected to support. This is done through usage flags.
For example:
VK_BUFFER_USAGE_VERTEX_BUFFER_BIT — the buffer can be used as a vertex buffer.VK_BUFFER_USAGE_INDEX_BUFFER_BIT — the buffer can be used as an index buffer.VK_BUFFER_USAGE_UNIFORM_BUFFER_BIT — the buffer can be read as uniform data by shaders.VK_BUFFER_USAGE_STORAGE_BUFFER_BIT — the buffer can be used as a storage buffer.VK_BUFFER_USAGE_TRANSFER_SRC_BIT — the buffer can be the source of a copy operation.VK_BUFFER_USAGE_TRANSFER_DST_BIT — the buffer can be the destination of a copy operation.Usage flags can also be combined. For example, a final vertex buffer uploaded through a staging buffer can be created with both
VK_BUFFER_USAGE_VERTEX_BUFFER_BIT and VK_BUFFER_USAGE_TRANSFER_DST_BIT.These flags do not define the memory itself. They define how Vulkan is allowed to use the VkBuffer.
A VkBuffer Is Not Its Memory
One of the first things I had to get used to is that Vulkan keeps the resource and the memory backing that resource as separate concepts.
A VkBuffer describes things such as how large the buffer is and what Vulkan is allowed to use it for. For example, a VkBuffer may be intended to receive transfer operations, contain vertex data or contain indices. But creating the VkBuffer does not automatically mean that memory has been allocated for it.
Problem: In native Vulkan, the general process is to create the VkBuffer, ask Vulkan what memory requirements it has, find a compatible memory type, allocate that memory and finally bind the allocation to the buffer.
Solution: Vulkan Memory Allocator
Vulkan Memory Allocator (VMA)
For STAGE VK I decided not to build a custom Vulkan memory allocator at this stage. Instead, I integrated Vulkan Memory Allocator. VMA does not replace Vulkan's memory model, it simply takes care of a lot of the repetitive work involved in finding suitable memory types and managing allocations.
That gave me a nice middle ground. I still decide what the VkBuffer will be used for, how it will be used, whether the CPU needs access to it and how it must be synchronized, while VMA handles the lower-level allocation work.
Adding the VulkanAllocator class
The first new piece of the backend is VulkanAllocator. It is intentionally a very small class. Its only real job is to own the VmaAllocator used by the rest of STAGE VK.
This also forced me to think more carefully about initialization order. The allocator needs the Vulkan instance, physical device and logical device, so it cannot exist before VulkanDevice has finished initializing. At the other end of the application's lifetime, every allocation created through VMA has to be destroyed before the allocator itself disappears, and the allocator must be destroyed before the Vulkan device.
That dependency now forms part of the Vulkan core lifecycle instead of being left implicit.
I also made the allocator follow the same ownership rules I am trying to establish throughout the engine: if the class owns the resource, it is responsible for releasing it.
That became much more important once I implemented the actual VulkanBuffer class.
Adding the VulkanBuffer class
VulkanBuffer became the engine-side owner of a VkBuffer and its VMA allocation. Besides the Vulkan handle itself, it keeps track of the allocation, size, usage flags and the memory properties selected by VMA.
Because a Vulkan allocation must have a single owner, VulkanBuffer cannot be copied. A normal copy would leave two C++ objects pointing to the same Vulkan resource, and both would eventually try to destroy it. Instead, the class is movable, so ownership can be transferred safely from one object to another.
This was also where RAII finally became much more concrete for me. My first implementation had a manual CleanUp() function, but the destructor did not call it. That worked until I deliberately tested an invalid CPU write that exceeded the buffer size. The range check threw an exception before the manual cleanup was reached, leaving the allocation alive. VMA later detected that leak when the allocator was destroyed.
The fix was simple but important: VulkanBuffer now releases its buffer and allocation from its destructor. If execution leaves a scope early, normal C++ stack unwinding destroys the object and cleans up the Vulkan resource automatically.
That gave me a much clearer ownership rule for the rest of the engine: If a class owns a resource, it also owns its cleanup.
There is still an important distinction, though. RAII controls the CPU-side lifetime of the resource; it does not know whether the GPU is still using it. Making sure a resource is no longer in flight before destroying it remains the engine's responsibility.
Note: RAII
RAII (Resource Acquisition Is Initialization) is a C++ ownership pattern where the lifetime of a resource is tied to the lifetime of the object that owns it.
In practice, this means that when an object owns a resource, its destructor is responsible for releasing it automatically when the object goes out of scope.
For VulkanBuffer, this means:
The VulkanBuffer object owns the VkBuffer and its VMA allocation.
The destructor releases both automatically.
The class cannot be copied, because two objects must not own the same Vulkan resource.
The class can be moved, which transfers ownership from one object to another.
If execution leaves a scope early, for example because of an exception, normal C++ stack unwinding still destroys the object and releases the resource.
A useful rule to remember is:
If a class owns a resource, it also owns the cleanup of that resource.
RAII only manages the CPU-side lifetime of the resource. The engine must still make sure the GPU is no longer using that resource before it is destroyed.
Letting the CPU Write to a Vulkan Buffer
Once VkBuffer creation was working, the next step was actually getting data into one.
For CPU-written buffers, STAGE VK now creates host-writable allocations through VMA. The engine requests memory that the CPU can access, while VMA selects an appropriate memory type for the current hardware and handles the mapping and any required cache flushing during writes.
The buffer still validates every write before passing the data to VMA. It checks that the resource exists, that its memory is host visible, that the input data is valid and that the requested range stays within the buffer bounds.
I tested this by writing a complete block of data, replacing a value at a specific offset and finally attempting an out-of-bounds write. The valid writes succeeded and the invalid one was correctly rejected.
At this point, STAGE VK could create a VkBuffer and fill it directly from the CPU. However, CPU-writable memory is not necessarily where I want long-lived rendering data to remain, which led to the next step: staging uploads.
Note: Host-Visible vs Host-Coherent Memory
Host-visible memory can be accessed by the CPU.
Host-coherent memory additionally guarantees that CPU writes become visible to the device without requiring an explicit cache flush.
These are separate memory properties. A memory allocation can be host visible without being host coherent, so STAGE VK does not assume that every CPU-writable buffer is automatically coherent.
Why I Needed a Staging Buffer
For data that will be read repeatedly by the GPU, I do not necessarily want the final allocation to remain CPU accessible. A static vertex buffer is a good example: the CPU may upload the vertices once, while the GPU could read them thousands of times afterwards.
This led to the staging upload path. Instead of writing directly into the final destination, STAGE VK first creates a temporary host-visible VkBuffer. The CPU writes the data into this staging buffer, and Vulkan then copies it into the destination buffer that will be used for rendering.
The staging buffer only exists for the duration of the upload. Once the copy has completed, it can be destroyed, while the destination buffer remains alive for its actual GPU-side purpose.
This separation also makes the role of each resource much clearer: the staging buffer exists to move data from the CPU, while the destination buffer exists to be consumed by the GPU.
The VulkanUploadContext class
I considered using the existing frame command buffers for uploads, but that would have mixed two different responsibilities. VulkanCommandContext is tied to the frame lifecycle: its command buffers are reset, recorded, submitted and reused continuously as frames progress. Resource uploads have a different lifetime, so I introduced a separate VulkanUploadContext.
It owns its own command pool, command buffer and fence, while currently submitting work through the existing graphics queue. The implementation is intentionally synchronous. When an upload is requested, it creates a temporary staging buffer, writes the CPU data into it, records a vkCmdCopyBuffer, adds the required synchronization for the destination resource, submits the command buffer and waits for the upload fence before returning.
The fence is what makes the temporary staging buffer safe to destroy afterwards. Recording vkCmdCopyBuffer only adds the copy operation to the command buffer; the GPU does not actually execute it until that command buffer is submitted to a queue. Waiting for the fence then confirms that the submitted work has finished.
This helped reinforce an important Vulkan distinction:
Recording a command is not the same as executing it, and executing it is not the same as knowing it has finished.
Why the Fence Matters
The staging buffer is temporary and exists only for the duration of the upload. Because it is a local RAII object, it will be destroyed automatically when the upload function returns, so the function must not finish while the GPU is still reading from it.
The upload fence solves that problem. After submitting the copy commands, the CPU waits for the fence to signal, confirming that the submitted GPU work has completed. Only then can the function return and safely allow the staging buffer to be destroyed.
This also helped me separate several Vulkan synchronization concepts that I had previously grouped together mentally. A memory flush makes CPU writes to non-coherent mapped memory visible to the device, a barrier establishes ordering and visibility between GPU accesses, and a fence allows the CPU to know when submitted GPU work has finished.
All three can be involved in the same upload, but they solve different problems. Once I separated those concepts, the upload process became much easier to understand.
Making the Uploaded Data Ready for Use
After the staging data has been copied into the destination buffer, that buffer will eventually be consumed by another part of the pipeline. A future vertex buffer, for example, may first be written by a transfer operation and then read by the vertex input stage.
Those two accesses need an explicit dependency, so VulkanUploadContext records a buffer memory barrier after the copy. The barrier tells Vulkan what kind of access just happened and what kind of access is expected next, allowing the destination buffer to be used correctly afterwards.
For the vertex-buffer test, this means making the transfer write visible before the vertex input stage reads the vertex attributes.
The part that helped me most was thinking of a barrier not as “pausing the GPU”, but as describing a relationship between resource accesses:
This resource was written here, and it will be accessed there next.
Because different buffers can have different consumers, VulkanUploadContext receives the destination pipeline stage and access mask instead of assuming that every uploaded buffer will be used in the same way.
Keeping the First Upload System Simple
This upload path is intentionally simple. Every upload currently waits for the GPU to finish before returning, which would not scale well for an engine continuously streaming large amounts of textures or geometry.
There are many ways this could evolve later, such as batching uploads, using a dedicated transfer queue, keeping persistent staging memory or moving uploads to an asynchronous system. I deliberately left those optimizations out for now.
At this stage, I wanted the upload API to have one very clear guarantee:
When the upload call returns, the destination buffer is ready to use.
That keeps resource lifetime and synchronization predictable while giving me a solid base for the next rendering systems.
Updating the Vulkan Core
After this work, the Vulkan core gained three important pieces: VulkanAllocator, VulkanBuffer and VulkanUploadContext.
VulkanModule now coordinates the allocator and upload context as long-lived backend systems, while VulkanBuffer provides the engine-side resource wrapper used to own individual VkBuffer resources and their VMA allocations.
The backend still manages the frame lifecycle, but it can now also support GPU resources whose lifetime extends beyond a single frame.
Integrating those systems also made resource lifetime more dependent on synchronization being handled correctly. Some waits, such as fence waits and vkDeviceWaitIdle, previously had their returned VkResult ignored. Those results are now checked before the engine assumes that GPU work has actually finished.

Shutdown follows the same dependency rules: GPU work is completed first, buffer resources and other VMA allocations are destroyed before the allocator, and the allocator is destroyed before the Vulkan device it depends on.
One Small Swapchain Improvement
While reviewing the Vulkan core, I also removed a couple of assumptions from the swapchain setup. It previously requested both color-attachment and transfer-destination usage without checking whether the surface supported them, and always selected opaque composite alpha.
The swapchain now requires color-attachment support because the current renderer depends on it, while transfer-destination usage is enabled only when available. Composite alpha is also selected from the modes reported by the surface, with opaque still preferred.
It is a small change, but it makes the backend less dependent on the capabilities of my current machine.
Where STAGE VK Is Now
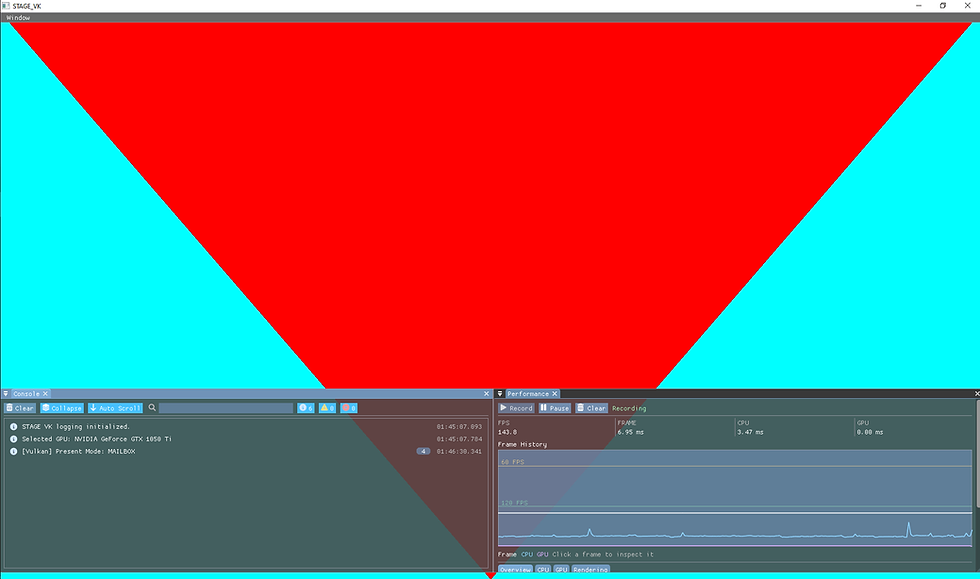
Visually, this implementation does not change much. STAGE VK still renders the same basic frame and editor UI, but the Vulkan backend can now create VkBuffer resources, allocate suitable memory for them, write data from the CPU and upload that data into GPU-oriented buffers through a staging path.
There is still no mesh renderer or model importing yet, and that is intentional. The goal of this chapter was to build the resource and upload layer those systems will depend on, instead of introducing buffer management, memory allocation and rendering all at once.
The biggest change for me was understanding that allocation, ownership and GPU lifetime are three separate problems. VMA helps manage the allocation, RAII ties the resource to its C++ owner, and synchronization determines when the GPU is actually finished using it.
With those responsibilities separated, STAGE VK now has the foundation needed to start storing and using real rendering data.


Comments